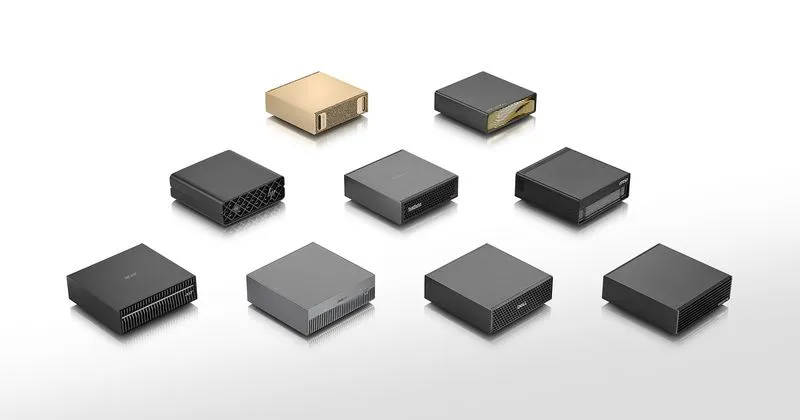
NVIDIA DGX Spark 64GB: $4,999 Local AI From Oct 23
- News
- Rocks on Galaxy
- Tech
- 03 Oct, 2026
- 0
Local AI just got a lower on-ramp. On October 2, 2026, NVIDIA announced a new 64GB unified-memory DGX Spark SKU that keeps the GB10 Grace Blackwell Superchip, DGX OS, and NVIDIA AI software stack of the existing 128GB personal AI supercomputer—at a partner price starting at $4,999.
Who sells it and when
- Available from Acer, ASUS, Dell, Gigabyte, HP and MSI
- Ship window: starting Friday, October 23, 2026
- Same ConnectX-7 networking and CUDA-accelerated stack as the 128GB model
- NVIDIA positions a single 64GB unit for models up to about 100 billion parameters on device
Popular local runtimes listed as day-one friendly include Ollama, vLLM, llama.cpp, LM Studio, and PyTorch with CUDA, plus NVIDIA Agent Toolkit and Nemotron open models.
NVIDIA Sync Cluster Assistant
Every DGX Spark includes ConnectX-7. Two 64GB systems can link with a QSFP cable; NVIDIA Sync Cluster Assistant detects the pair, validates config, and sets up the fabric so memory pools to 128GB (NVIDIA says support expands toward ~200B-parameter models with roughly 2× memory bandwidth). In NVIDIA’s own Qwen 3.8 27B test, two clustered 64GB systems delivered up to 1.7× the performance of one unit—treat that as a vendor benchmark, not a guarantee.
Later in October, NVIDIA plans Sync Model Launcher to download/launch Qwen3.8 27B on one box or a cluster and wire OpenCode for browser coding.
Rocks take
This is the compact DGX Spark appliance line—not the consumer RTX Spark Windows PCs also shipping this month. Source: NVIDIA blog Oct 2.
What stays the same vs 128GB
NVIDIA is explicit that the 64GB SKU is not a cut-down chip: GB10 Grace Blackwell, DGX OS, ConnectX-7, and the CUDA-X / Agent Toolkit stack match the 128GB personal AI supercomputer. The dial that moves is unified memory capacity—and therefore which model sizes fit before you reach for a second box. Partner OEMs (Acer, ASUS, Dell, Gigabyte, HP, MSI) handle the chassis and channel; NVIDIA quotes a $4,999 starting price for October 23 availability.
For Rocks readers running local agents: Ollama, vLLM, llama.cpp, LM Studio, and PyTorch+CUDA are called out as ready paths. Blender is preparing a downloadable installer. Sync Model Launcher—still “later in October” as of the Oct 2 post—aims to one-click Qwen3.8 27B across a single unit or a cluster and hand it to OpenCode in the browser.
FAQ
Is $4,999 the street price forever? NVIDIA quotes partner starting prices; memory markets can move MSRPs.
Do I need two units on day one? No—start with one 64GB system and cluster later if workloads outgrow it.