CoreWeave Vera Rubin NVL72 Live: Cognition 4.8x Oct 2026
- News
- Rocks on Galaxy
- Tech
- 02 Oct, 2026
- 0
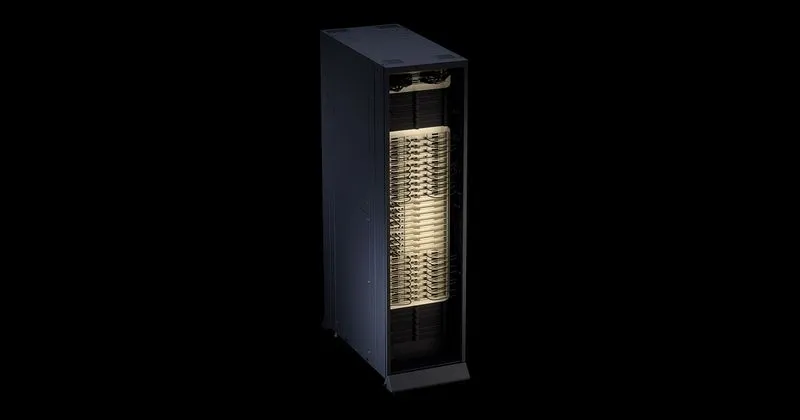
Vera Rubin left the roadmap. On September 30, 2026, CoreWeave announced that NVIDIA Vera Rubin NVL72 is available on CoreWeave Cloud, with Cognition—the lab behind coding agent Devin—as the first customer anywhere running production workloads on the rack-scale system.
What Cognition measured
- Up to 4.8× total token throughput on SWE-2 inference vs a GB200 NVL72 baseline (Cognition engineers)
- 3.8× output-token throughput for reinforcement-learning workloads
- Cluster stood up in early September; announcement at Fully Connected in San Francisco
CoreWeave separately published silicon measurements claiming 10× token throughput per megawatt versus GB200 NVL72 on DeepSeek R1 at matched interactivity. Treat both sets as vendor/customer-reported until independent labs replicate them.
Platform context
Vera Rubin NVL72 unifies Rubin GPUs and Vera CPUs over NVLink 6 in an NVL72 rack. Cognition runs training, RL, and production inference for Devin on CoreWeave and scaled to thousands of GPUs in under nine months. Access is limited availability, not open self-serve; neither CoreWeave nor NVIDIA published public $/GPU-hour pricing with the launch.
Rocks take
Dated production milestone for the post-Blackwell rack—distinct from consumer RTX Spark coverage. Sources: CoreWeave newsroom; NVIDIA corroboration on the partnership.
FAQ
Can anyone spin up Vera Rubin today? CoreWeave frames it as limited availability for selected customers.
Is 4.8× a general speedup? No—it is Cognition’s SWE-2 inference result versus GB200 NVL72 on their workload.